

There is no shortage of hype about artificial intelligence in the evaluation world these days, and equally no shortage of evaluators quietly muttering that this, too, shall pass, like blockchain and Big Data before it. From Algorithms to Evidence: Using GenAI in Evaluation Practice, edited by Kerry Bruce, Valentine Joseph Gandhi, and Steffen Bohni Nielsen, is refreshingly uninterested in either position. It does not sell generative AI as salvation, and it does not dismiss it as a fad. Instead, across 34 chapters and roughly 30 field-tested case studies, it asks a much more useful question: what actually happens when working evaluators put GenAI into real evaluation workflows, and what should the rest of us learn from it before we do the same.
The book is the sequel to Artificial Intelligence and Evaluation: Emerging Technologies and Their Implications for Evaluation (Nielsen, Mazzeo Rinaldi, & Petersson, 2025), and it sits in Routledge’s long-running Comparative Policy Evaluation series, edited by Andrew Koleros, Frans L. Leeuw, Ida Lindkvist, and Ray C. Rist. Where the first volume mapped the terrain, this one drives through it. Made open access thanks to a Hilton Foundation grant, it is worth reading in full, but for practitioners with limited time, here is what an evaluator’s eye finds most useful.
What the Book Actually Covers
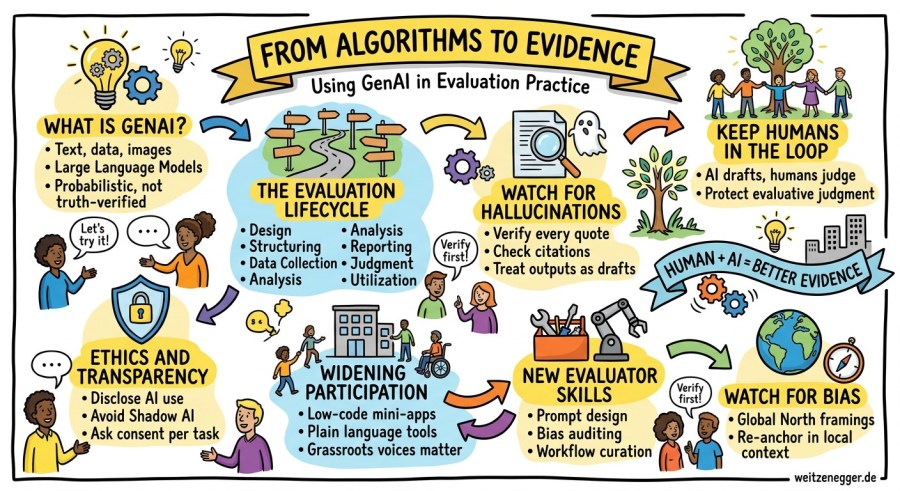
The editors organize the volume around the seven phases of the evaluation lifecycle: design, structuring and inception, data collection, data analysis, reporting, judging, and utilization. Each phase is populated with concrete case chapters from organizations as varied as the World Bank Independent Evaluation Group, UNDP, IFAD, CGIAR, the Global Environment Facility, a Minneapolis grassroots nonprofit, and a Hungarian ministry auditing EU funds. This range matters: it means the book is not written only for well-resourced UN agencies, nor only for solo consultants. Both extremes get real airtime.
Four crosscutting chapters close the volume, and they are arguably its intellectual spine. Montrosse-Moorhead and David synthesize where “methodological automation ends and judgment begins,” and their empirical finding deserves to be quoted by every evaluator drafting an AI policy for their organization: across all the case chapters analyzed, GenAI use clusters heavily in descriptive and analytic tasks and is essentially absent from evaluative judgment itself. In plain terms, the tool drafts, sorts, and summarizes; it does not, and should not, decide what something means. Tessie Catsambas then addresses evolving evaluator competencies, Ananda Millard and Tom Ling take on ethics and professional standards, and Gandhi, Bruce, and Nielsen introduce FRAME, a practical framework for responsible AI use across the evaluation lifecycle, which reads as the book’s attempt to give the field something it can actually adopt rather than merely admire.
Frans Leeuw’s foreword adds a welcome note of historical perspective, situating today’s GenAI anxieties alongside earlier waves of algorithmization dating back to educational evaluation research in the 1970s, and gently needling the field’s “new Luddites” who have spent conferences arguing about whether AI is worth engaging with at all-
Three Themes That Matter for Practice
Methodological adaptation is real, but it is additive, not substitutive. The strongest case chapters show GenAI reshaping how evaluators do things, not replacing why or whether they do them. Hailemichael Taye Beyene’s chapter on a mixed-methods SDG 1 evaluation across Sub-Saharan Africa is a standout example: using fsQCA (fuzzy-set qualitative comparative analysis), the author used ChatGPT to help reduce 22 inductively derived factors down to 10 analytically robust conditions, with the AI proposing groupings, terminology, and causal simulations at each step. Crucially, every retention or exclusion decision remained evaluator-led, and several AI suggestions were explicitly rejected, for example, because a proposed condition overlapped analytically with another or because the AI’s initial framings missed African political and cultural nuance, including informal political settlements and donor-government bargaining dynamics that reflected Global North assumptions baked into the training data.
Competencies are shifting toward orchestration, not disappearing. Several chapters converge on the same lesson: the skills that matter now are prompt design, workflow curation, source verification, and bias auditing, layered on top of the “traditional” evaluator toolkit rather than replacing it. In the grassroots nonprofit case (Chapter 2, Paschke), the evaluator became a manager of a small ecosystem of tools, a custom AI assistant, vibe-coded mini-apps for stakeholder engagement, and a NotebookLM-generated multimedia explainer, while retaining full responsibility for contextualization and quality control.
Ethics is where the book earns its keep. This is not a rehash of generic AI-ethics talking points. It surfaces specific, occupational risks: hallucinated citations and quotations, “semantic drift” where AI-suggested rewordings quietly shift the meaning of a construct across iterations, automation bias (the tendency to accept AI output without scrutiny), and what Steve Jacob’s chapter memorably calls “shadow AI,” meaning undeclared or informal AI use in reports and reviews that erodes professional accountability. One case candidly admits that a client’s consent for AI assistance was obtained for some deliverables but not others mid-project, a transparency gap the author uses to argue that consent for AI use must be sought iteratively, not assumed from an initial blanket approval.
Down-to-Earth Hints for Practitioners
Having read this as someone who spends a fair share of professional life drafting terms of reference, coding interview transcripts, and defending methodology sections to commissioning agencies, here is what I would actually take into the field.
- Treat every AI output as a first draft, never a source. The book is consistent on this point across a dozen chapters: GenAI outputs are probabilistic continuations of text, not verified facts. Build a verification step into your workflow for anything AI touches, especially quotations, statistics, and citations, before it goes anywhere near a report.
- Log your prompts and your decisions, not just your findings. The fsQCA case shows the value of a structuring decision matrix that records what the AI suggested, what the evaluator accepted or rejected, and why. This is not bureaucratic overhead; it is what makes an AI-assisted analysis defensible under peer review or audit.
- Keep AI out of evaluative judgment. Use it to draft, cluster, summarize, and translate; do not let it score, rank, or conclude. The cross-chapter finding that GenAI use concentrates in descriptive and analytic phases, and stays out of judgment phases, is worth adopting as a house rule.
- Watch for Global North bias in generic outputs, particularly in country-context work. If an AI-generated governance framing or theory of change feels a little too tidy or too universal, that is often a sign it needs re-anchoring in local evidence and stakeholder voice.
- Get consent for AI use per deliverable, not once at kickoff. Clients and commissioners should know when and how AI touched their materials, chapter by chapter if necessary. Silence on this is how “shadow AI” creeps into a field that depends on trust.
- Match the tool to the task and the budget, and expect to switch. The grassroots nonprofit case tested Claude, Gemini, and ChatGPT before settling on ChatGPT’s Projects function for document continuity, then later moved to Claude as needs changed. Do not marry one platform; evaluate your tools the way you evaluate everything else.
- Use lightweight, low-code tools to widen participation, not just to save your own time. Vibe-coded mini-apps, decision cards, and NotebookLM walkthroughs were used in several chapters specifically to bring non-specialist staff and grassroots stakeholders into technical decisions they would otherwise be excluded from. That is a genuine equity gain, not just an efficiency one.
- Build AI literacy into your own professional development now. Several chapters argue this is no longer optional. You do not need to become a data scientist, but you do need to understand prompt sensitivity, model drift across versions, and the basic mechanics of why an LLM can sound authoritative while being wrong.
A Fair Assessment
The book’s honesty is its greatest strength. It does not pretend every case was a success, and several authors report false starts, rejected outputs, and workflow dead ends alongside the wins. Leeuw’s foreword raises a fair critique, too: the volume says relatively little about AI’s potential role in analyzing the vast, largely unheard body of citizen and grassroots testimony that development agencies rarely systematize, an opportunity for a future volume rather than a flaw in this one. For evaluators in Germany and across the EU working with tight data protection rules, it is also worth noting most case studies draw on public, non-sensitive documents; readers doing sensitive fieldwork will want to pay close attention to the chapter on self-hosted, data-secured AI solutions (Bustamante Aragonés) rather than assuming commercial cloud tools are automatically fit for purpose.
For evaluators, MEL practitioners, and commissioning agencies trying to move past the hype cycle and the panic cycle alike, this is the most grounded, practice-tested reference available right now.
Reference: Bruce, K., Gandhi, V. J., & Bohni Nielsen, S. (Eds.). (2027). From Algorithms to Evidence: Using GenAI in Evaluation Practice. Comparative Policy Evaluation series. New York, NY: Routledge. DOI: 10.4324/9781003799139. Available via Routledge.